Tagline
NLP pipeline mining Reddit's car subs for sentiment and topic shifts.
Tech Stack
Python, Pandas, NLTK, Gensim, Scikit-learn, PRAW, Django, Next.js
Year
2026

NLP pipeline mining Reddit's car subs for sentiment and topic shifts.
Python, Pandas, NLTK, Gensim, Scikit-learn, PRAW, Django, Next.js
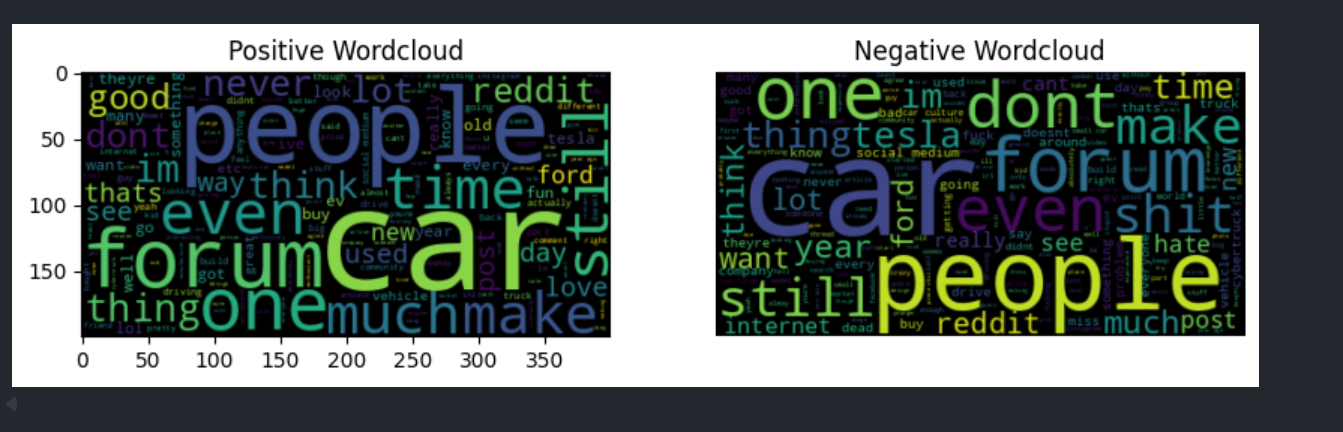
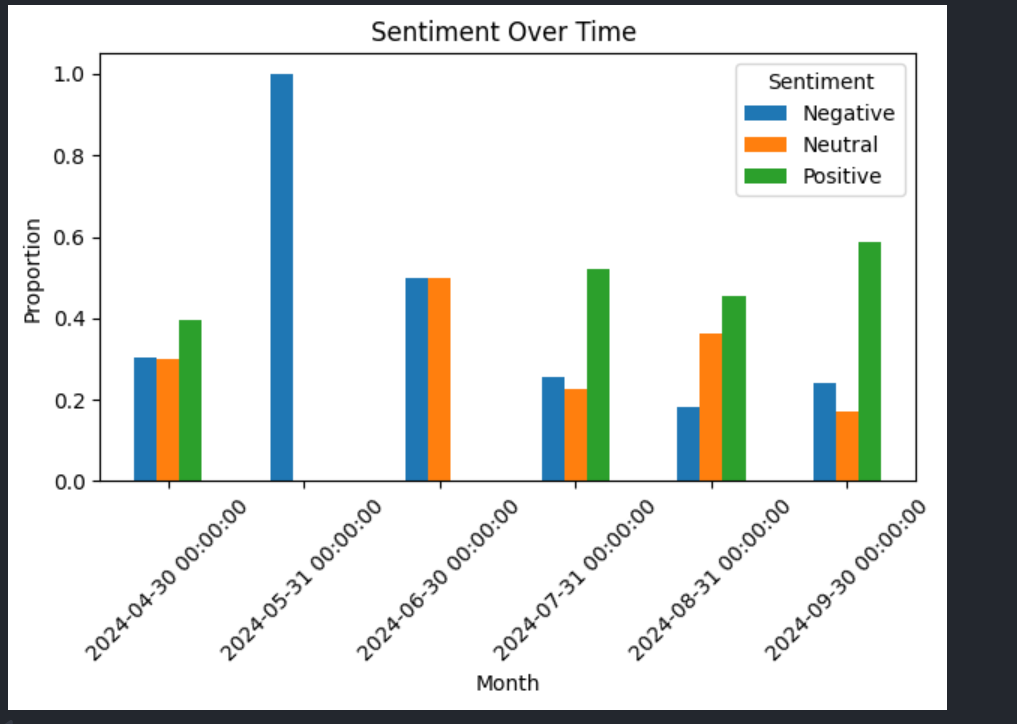
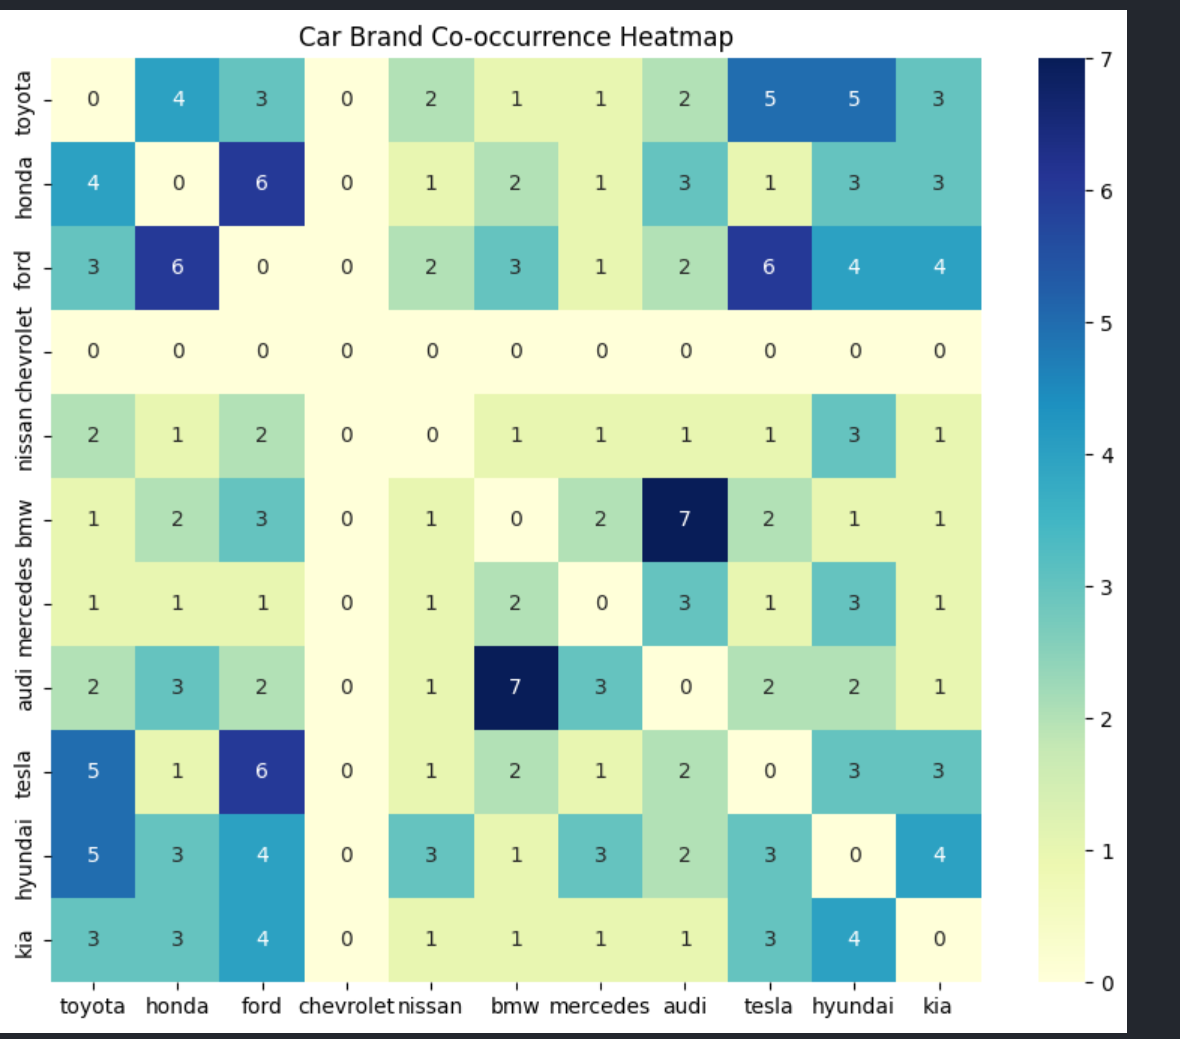
TorqueLens pulls 2,000 plus comments from five automotive subreddits and runs them through a proper NLP stack: tokenisation, stopwords, WordNet lemmas. VADER handles sentiment scoring, and two topic models (LDA on bag-of-words, NMF on TF-IDF) cross-check each other so the themes actually hold up. Output lands as wordclouds, sentiment bands over time, and an eleven-brand co-occurrence matrix. A Django API and Next.js client scaffold the dashboard around it.
PRAW scrapes 2,000+ comments across /r/cars, /r/electricvehicles, /r/whatcarshouldIbuy and two more car-focused subreddits. Raw text is persisted for reproducible runs.
PRAW · Reddit API
tap a step to explore →
Car buyers argue endlessly on Reddit, and there's real signal in it — which brands people trust, how sentiment shifts, what themes cluster together. But it's buried in thousands of noisy, sarcastic, unstructured comments that no dashboard reads for you.
A full NLP pipeline: PRAW pulls 2,000+ comments across five automotive subreddits; NLTK handles tokenisation, stopword removal and WordNet lemmatisation; VADER scores sentiment; and two topic models — LDA on a bag-of-words corpus and NMF on a TF-IDF matrix — surface latent themes. On top sit fuel-type classification and an eleven-brand co-occurrence matrix, visualised as wordclouds, sentiment bands over time and a brand heatmap, with a Django API feeding a Next.js dashboard.
The judgement call was whether one topic model was enough. A single model's topics can be artefacts of its assumptions — you can't tell a real theme from noise. I ran LDA and NMF side by side and only trusted themes both methods agreed on. It cost extra compute and interpretation time, but it's the difference between reporting findings and reporting coincidences.
Cross-validating the two models gave themes I could actually stand behind. The weak link is VADER: it's fast and lexicon-based, so it misses the sarcasm that's everywhere in car forums. The next step would be trialling a transformer sentiment model and measuring how much the sarcasm-heavy comments were being misread.
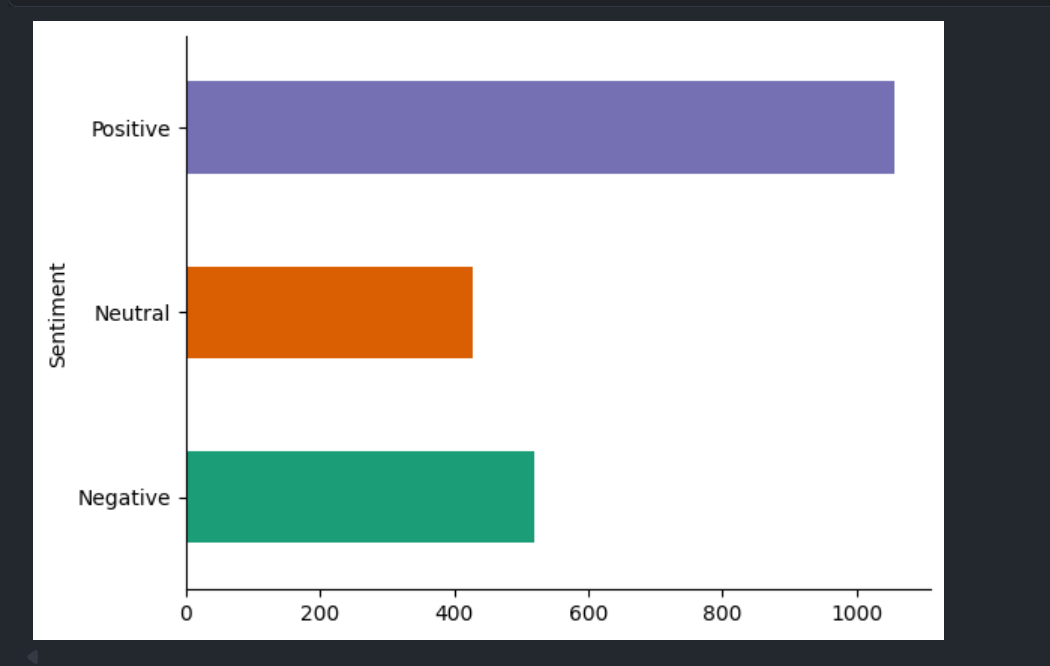
TorqueLens collects 2,000+ comments across /r/cars, /r/electricvehicles, /r/whatcarshouldIbuy and related subreddits via PRAW, then runs a full NLP stack — URL stripping, NLTK tokenisation, stopword filtering, and WordNet lemmatisation. VADER compound scores classify each comment as positive, neutral, or negative; dual topic modeling (LDA on a bag-of-words corpus and NMF on a TF-IDF matrix) cross-validates the latent themes. Feature extraction adds fuel-type classification (gas / diesel / electric / hybrid) and an 11-brand co-occurrence matrix, surfacing which marques drivers discuss together.